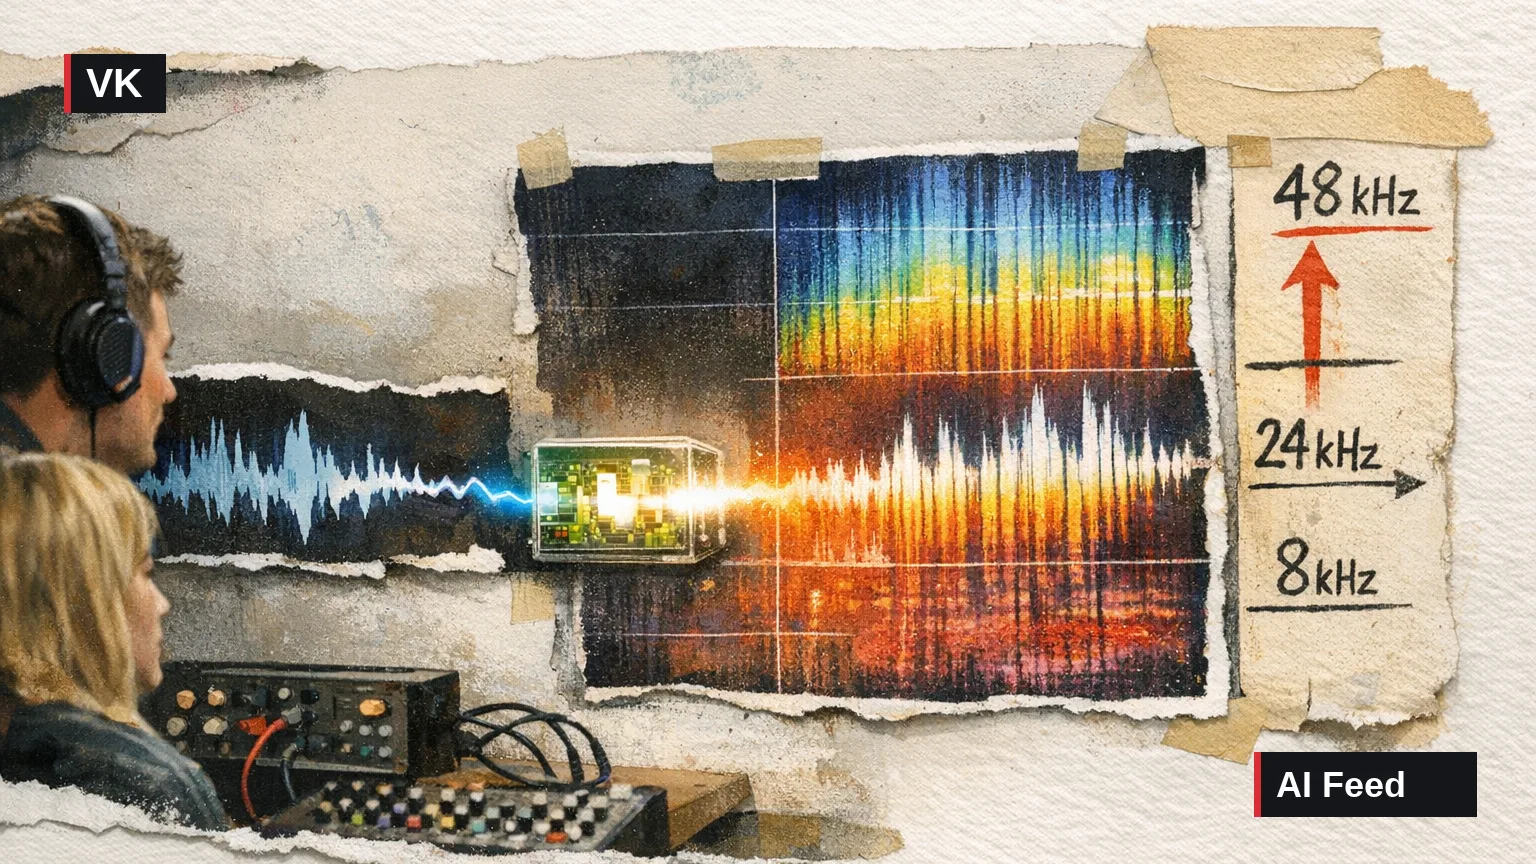
VK on September 16 presented FastWave, a compact diffusion model designed to reconstruct missing high-frequency audio components while raising the sampling rate to 48 kHz. The project was developed through the AI Services and Platforms workshop run by the HSE University School of Engineering and Mathematics and VK. According to the team, the model accepts audio recorded at different source sampling rates.
FastWave contains 1.3 million parameters and requires 12.9 GFLOPs per model call. Its main configuration uses four sequential calls, putting the stated total computational cost at about 50 GFLOPs. The underlying NU-Wave 2 model has 1.8 million parameters, requires 19 GFLOPs per call and normally runs for eight generation steps.
To reduce the model, the developers adapted the EDM methodology to audio. Their changes included predicting the clean signal rather than noise, scaling inputs and outputs according to noise level, using a log-normal distribution of training noise levels, applying a weighted L2 loss and adopting a continuous generation schedule. They also replaced conventional convolutions with separable convolutions and added Global Response Normalization for cross-channel interaction. The team said these changes cut the parameter count by 30% from NU-Wave 2 while preserving reconstruction quality in its experiments.
Training used the VCTK speech dataset, which contains recordings from 110 speakers and about 44 hours of 48 kHz audio. One hundred speakers were assigned to training and eight to testing. The team evaluated conversion from 8, 12, 16 and 24 kHz to 48 kHz; training on a single NVIDIA V100 GPU took up to 30 hours.
In the 24-to-48 kHz comparison, four-step FastWave recorded an SNR of 27.09 and an LSD of 0.93. Eight-step NU-Wave 2 reached 27.68 and 0.78, while one-step FlowHigh reached 27.80 and 0.74. FastWave therefore did not lead on either metric, but it was smaller, with 1.3 million parameters compared with FlowHigh’s 49.4 million.
Practical context: FastWave represents a trade-off among model size, sequential computation and measured reconstruction quality. The reported results suggest potential for streaming speech processing on GPU-equipped devices, but the source provides no tests on CPUs, mobile accelerators, music or audio beyond the VCTK speech dataset. All measurements were published by the development team, and the article does not describe independent reproduction.
The developers released the code and a pretrained checkpoint on GitHub through links on the project page. They also said the FastWave research paper had been accepted for the Interspeech 2026 conference.
| Model | NFE | SNR ↑ | LSD ↓ |
|---|---|---|---|
| AudioSR | 1 | 23.03 | 1.27 |
| FlowHigh | 1 | 27.80 | 0.74 |
| NU-Wave 2 | 8 | 27.68 | 0.78 |
| FastWave | 4 | 27.09 | 0.93 |
| FastWave | 8 | 27.22 | 0.83 |
| Model | NFE | SNR ↑ | LSD ↓ |
|---|---|---|---|
| NU-Wave 2, baseline | 8 | 17.47 | 1.31 |
| NU-Wave 2 + EDM | 4 | 16.72 | 1.25 |
| NU-Wave 2 + EDM | 8 | 16.02 | 1.21 |
| FastWave | 4 | 18.49 | 1.22 |
| FastWave | 8 | 18.10 | 1.26 |
How to read the comparison metrics
SNR is the signal-to-noise ratio, for which a higher value is considered better. LSD measures the distance between spectra, for which a lower value is considered better. NFE indicates the number of sequential model calls used during generation.
Sources
Event date: 2026-09-16. Primary source date: 2026-09-16.