VK on August 27 described using its multitask DCDN neural ranker in the Discovery platform’s recommendation system. According to the company, the architecture replaces gradient-boosted decision trees at the final content-ranking stage and learns nonlinear relationships directly from raw data, reducing the need to engineer numerous features manually.
Before final ranking, a two-tower model and the cross-domain Heimdall model assemble a pool of several thousand candidates for each user. DCDN then combines high-dimensional transformer embeddings with current contextual features and calculates scores for ordering the feed. Interaction feedback, including clicks, completed views and skips, is logged and returned to the platform’s cloud training infrastructure for regular model updates.
Continuous input features undergo piecewise-linear encoding. Each feature’s range is divided into buckets based on how frequently values occur in logs, and a value is represented through a convex combination of trainable vectors at the neighboring boundaries. The DCDN core builds on Deep & Cross Network techniques to model feature combinations while keeping the representation’s dimensionality fixed across cross blocks.
VK identifies a built-in division operation as a central change to the architecture. It is intended for relative signals such as click-through rate and the share of completed views. The company says DCDN can derive these relationships from raw click, impression and view counters, rather than requiring engineers to create ratio features manually.
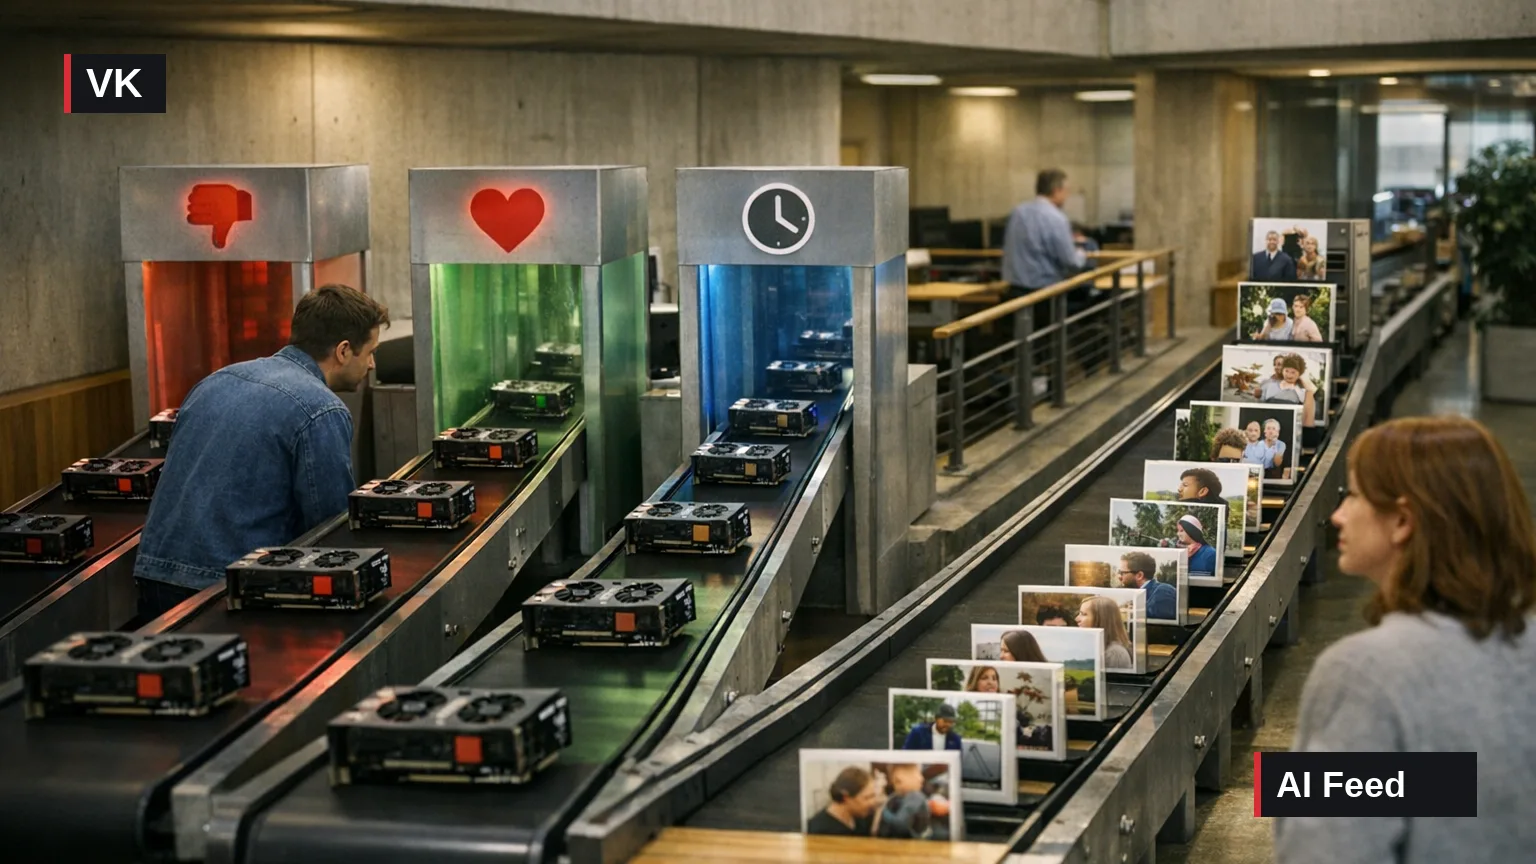
The model has three independent output heads: the probability of a like, the risk of a dislike or content hide, and expected engaged watch time. Their gradients are isolated with stop_gradient, while a separate compact learning-to-rank network combines the predictions into the final score. VK says the signal combination used for final sorting can be changed at runtime without retraining the shared core.
For watch time, the team moved away from regression based on mean squared error. Instead of producing one average estimate, the model predicts a hierarchical mixture comprising an exponential distribution for rapid skips and Gaussian distributions for engaged viewing. To counter collapsing variances during likelihood-based training, VK used evenly distributed initialization of Gaussian means and a regularization penalty tied to divergence from the empirical distribution.
Practical context: VK reported that probabilistic watch-time modeling increased total watch time in VK Clips by 5.5%, likes by 5% and shares by 15%, with no decline in other metrics. These are results from VK’s own case study; the page does not provide an independent reproduction or describe the experimental design. Within the scope of VK’s account, the approach is potentially relevant where ranking objectives have distinct behavioral modes and many features are ratios.
| Model output | Prediction |
|---|---|
| Like | Probability of an explicit like |
| Negative reaction | Probability of a dislike or content hide |
| Viewing | Expected engaged watch time |
Sources
Event date: 2026-08-27. Primary source date: 2026-08-27.